3-Line TL;DR
- I moved from Astra to Opus 5.5 because the output is better and the tokens are 60% cheaper
- In a same-prompt test of two games, Opus won both rounds, but the bills split one each
- Hand visible, finished work to Opus, but judge it by what each task actually cost
Astra's launch party was short
- When Astra launched, my first thought was that Fable should get nervous
- Since Opus 5.5 arrived, my pick for both value and output has moved to Opus
- In my use, Opus 5.5 also feels roomier on usage
- That is a felt impression from daily use, not a measured limit or a controlled test
- Turns out the one that needed to get nervous was Astra, not Fable
Same prompt, only Opus got excited
- Moe Lueker gave both models the same prompt for two games and allowed no fixes (Moe Lueker, September 25)
- Both started in an empty folder, Astra in Codex and Opus in Claude Code
- Round 1 was a runner, and Round 2 was a cozy island builder
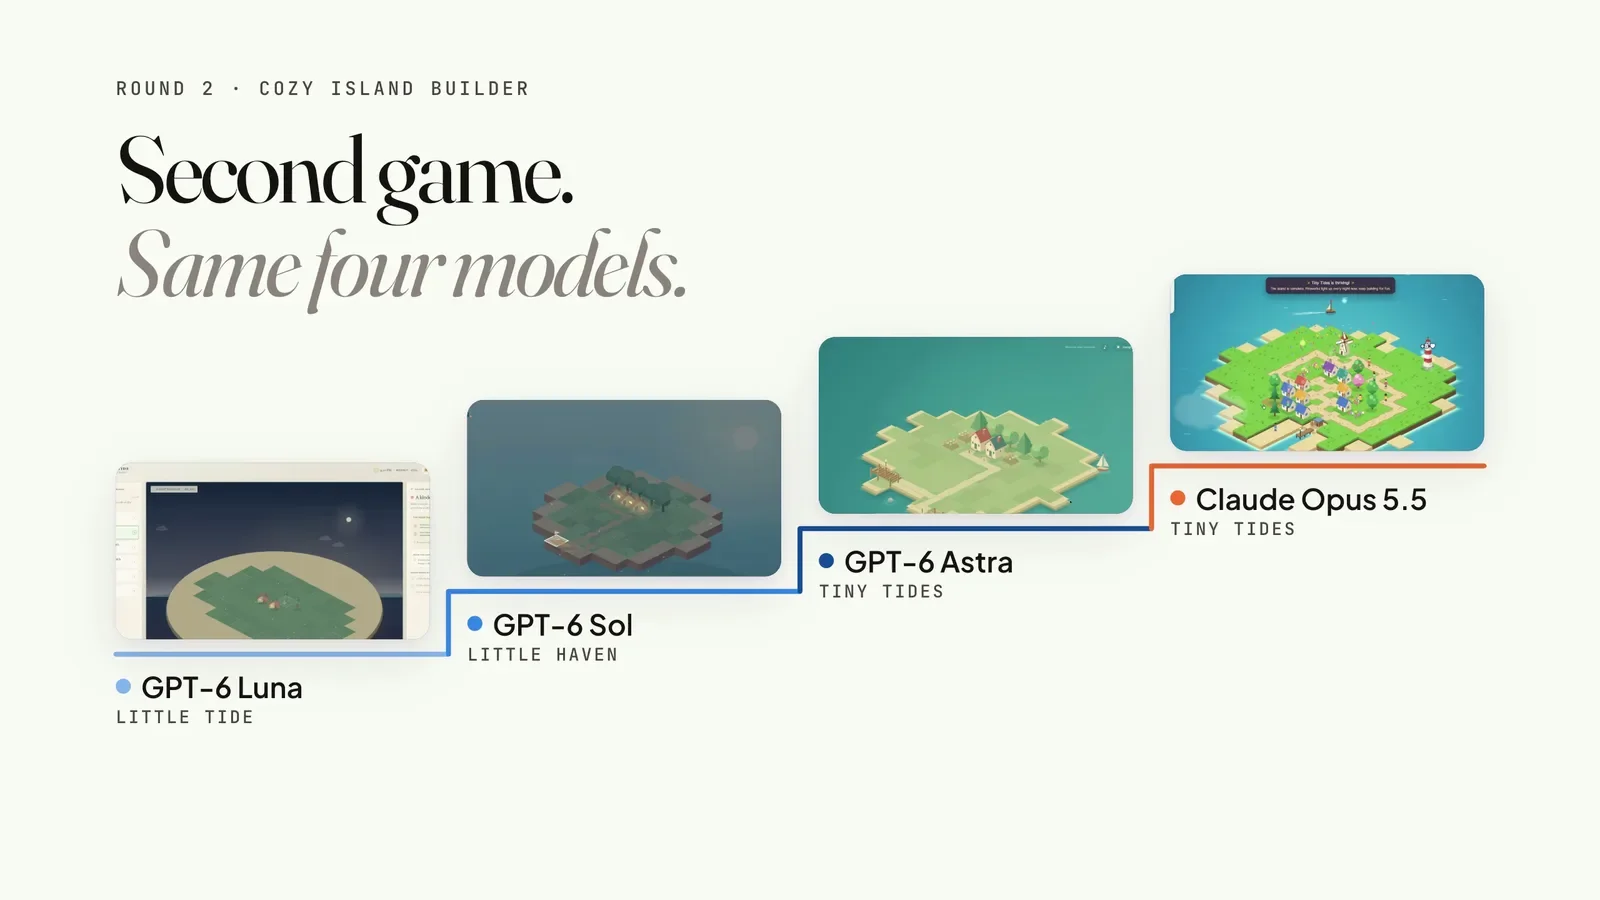
Source: Moe Lueker — Claude Opus 5.5 vs GPT-6 Astra: Same Prompt, Two Games, Real Cost
- In the runner, Opus added diving, braking, sprinting, checkpoints and background music
- Nobody asked for any of it
- Astra's runner had real art and a parallax background, the best GPT-6 build by the tester's account
- Opus wrote 2,405 lines of game code, and Astra wrote 358
- On the island, Opus grew the land as you built, added a night mode and rewarded houses next to paths
- Astra's island had more tree and house types, and that was about it
- One tester ran each model once per round, so treat it as a case, not a benchmark
60% cheaper tokens, double the bill
| Model | Input per 1M tokens | Output per 1M tokens |
|---|---|---|
| GPT-6 Astra | $10 | $50 |
| Claude Opus 5.5 | $4 | $20 |
Standard API rates, Astra short-context tier, checked September 28, 2026: OpenAI pricing, Anthropic
- Opus lists 60% lower than Astra on both input and output
- Anthropic says Opus 5.5 at medium effort scored 54.6% on FrontierCode, above Astra's best 53.3%, at about a fifth of the cost per task
- Anthropic graded and published that report card itself, so read the settings too
- The same page puts Astra ahead on AutomationBench, 41.4% to 40.0%
- Credit where due, it published the loss on its own launch page
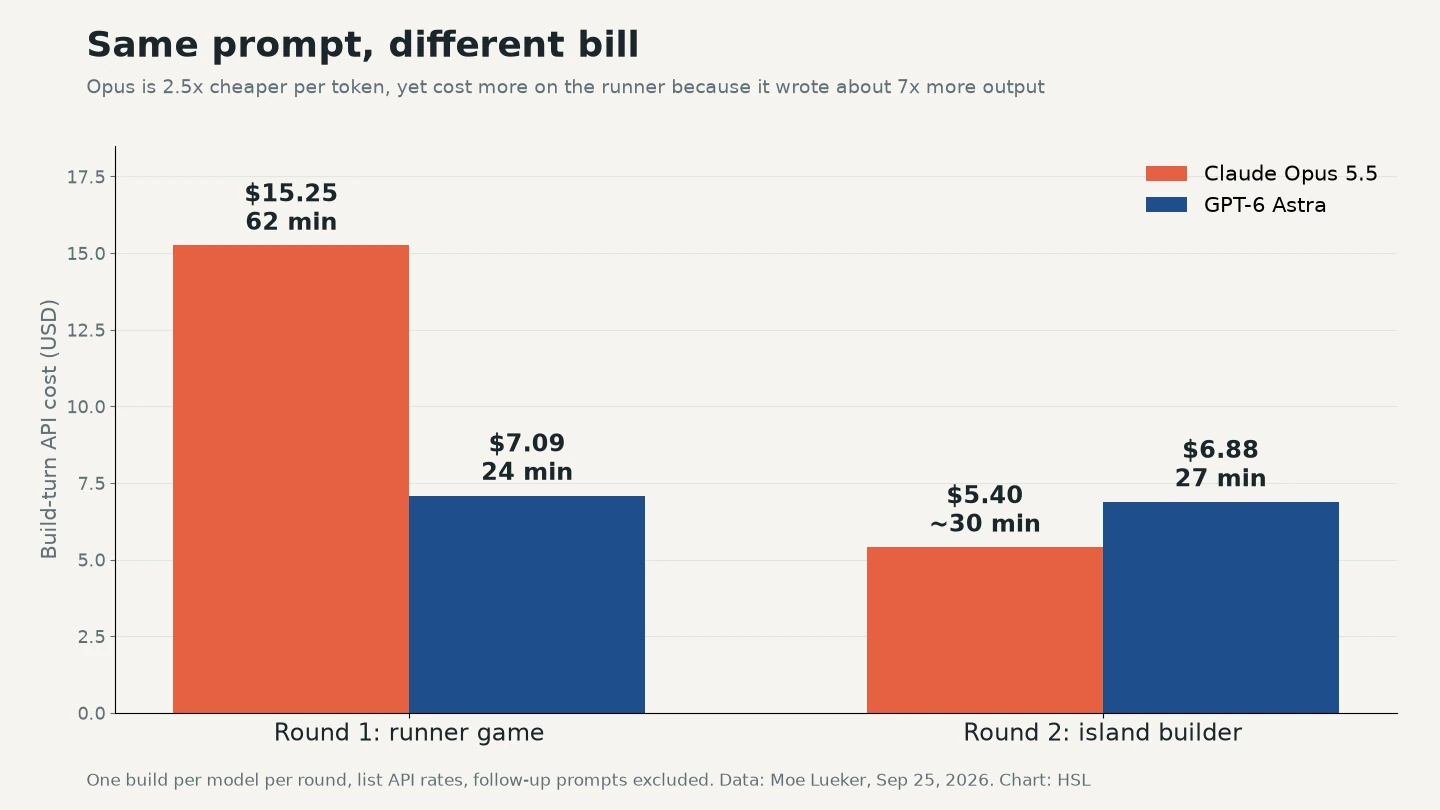
Data: Moe Lueker, build turn only at list API rates — chart by HSL
- On the runner, Opus wrote 256K output tokens to Astra's 36K, and the bill was $15.25 against $7.09
- A 60% discount does not survive seven times the work
- On the island builder, the bill flipped to $5.40 for Opus and $6.88 for Astra
- Across both games, Opus cost $20.65 and Astra $13.97, about $7 more for two better games
- The unrequested background music was billed down to the last token
So who gets which job?
| Job | Start with | Why |
|---|---|---|
| Front end, design, games | Opus 5.5 | Better result in both same-prompt rounds |
| Long back-end debugging | Compare with Astra | The same tester keeps Astra for back end, and one Reddit report below agrees |
| Fixed budget | Set a cap first | Opus may build more than you asked for |
- Put a token or spending cap on long Opus runs before you start
- It adds a soundtrack on its own initiative, so a human should set the budget
- Divide total spend by accepted tasks instead of reading the rate card
- Keep asking Astra about the problems where Opus stalls
Community Reactions
- An r/codex author found Opus productive but rated Astra and Fable higher for deep async-runtime design, a real counterexample to "Opus wins everything" (Reddit)
- Another commenter in the same thread said Opus fixed a bot that Astra failed to fix after using a lot of quota, which is one person's experience rather than a measured bill (Reddit)
Q&A (Field Notes)
- Q. Is Opus 5.5 always cheaper than Astra?
- Per token yes, but per task it depends on how excited Opus gets about the job
- Q. Does one same-prompt test prove Opus is better?
- No, one tester ran each model once per round, so repeat it on your own work
- Q. Can I rerun the exact test?
- The prompt is not published, so match the empty folders and effort settings and use your own prompt
- Q. Should I drop Astra entirely?
- Not if you do long back-end debugging, where both the tester and a Reddit report still reach for it