3-Line TL;DR
- Behind OpenAI and Anthropic, Artificial Analysis puts Meta's Muse Spark 1.3 first at 48, with Grok 4.7 and Xiaomi's MiMo-V2.6-Pro at 46, while Opus 5.5 leads everyone at 58
- "Chinese AI is cheap" holds for Xiaomi and DeepSeek at $0.13 and $0.27 per index task, but Qwen3.8 Max, GLM-5.3 and Kimi K3 cost more per task than Opus 5.5 at high effort
- Anthropic's September report accuses all five Chinese labs in this comparison of distilling Claude, so check where your prompts go before comparing prices
The second tier's best ties OpenAI's middle model
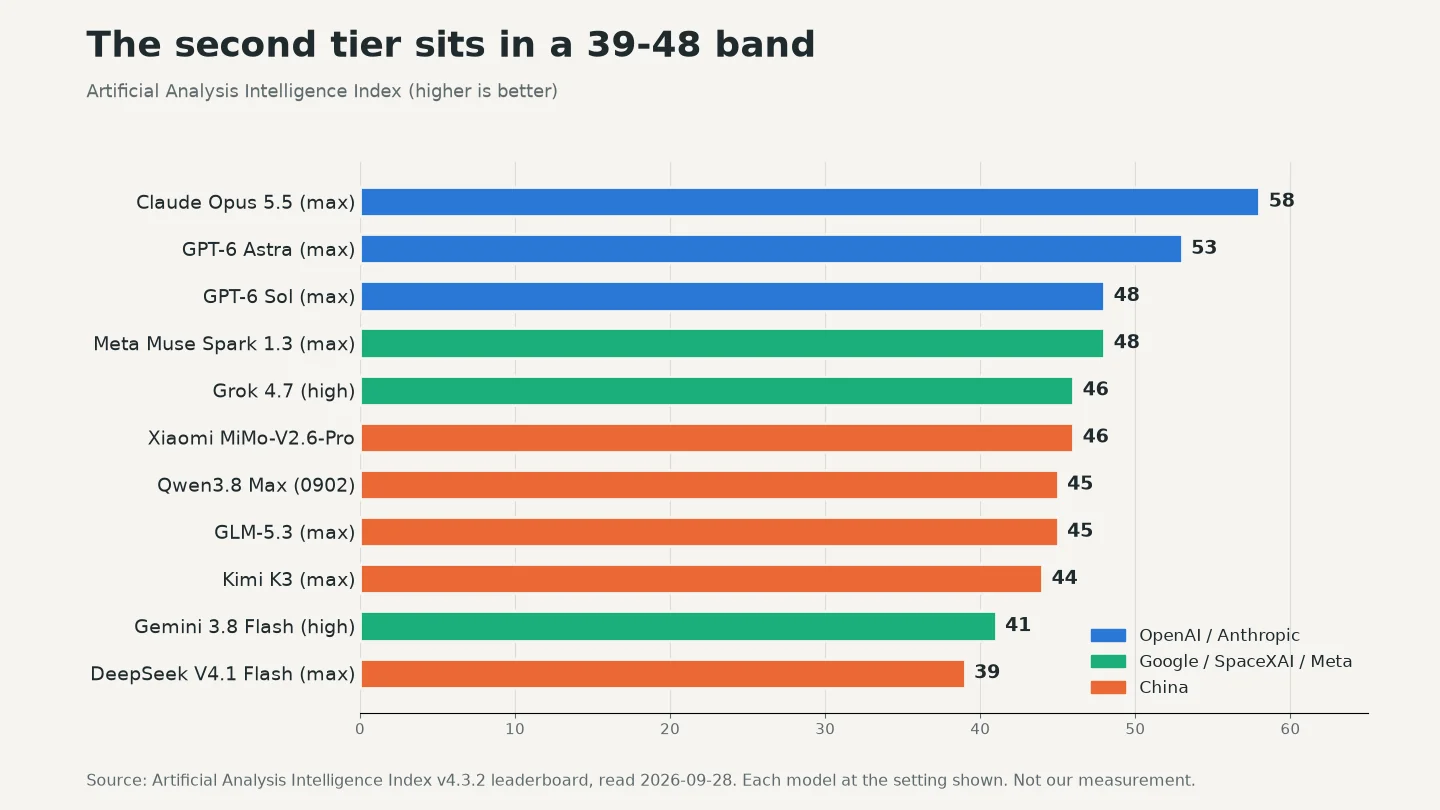
Source: Artificial Analysis — Intelligence Index v4.3.2 leaderboard, read September 28, 2026 — chart by HSL
- Artificial Analysis runs every model itself on ten evaluations, including GDPval, Terminal-Bench 4.0 and Humanity's Last Exam, and combines them into one index (methodology)
- Opus 5.5 at max effort leads with 58, and GPT-6 Astra follows at 53
- In this chart, eight models from eight other companies land between 39 and 48
- Meta's Muse Spark 1.3 tops that group at 48, the same score as GPT-6 Sol
- Sol is OpenAI's middle tier
- The same model moves three points between effort settings (Muse Spark 1.3: 45 at xhigh, 48 at max), so treat 44–46 as one cluster
- Google's best entry is Gemini 3.8 Flash at 41, because its newest Pro model is still the 3.1 Pro preview (Google), which scores 30
- Google's answer is Gemini 4, which still has no date (what we know about the Gemini 4 release)
Chinese AI is cheap at only two of five labs
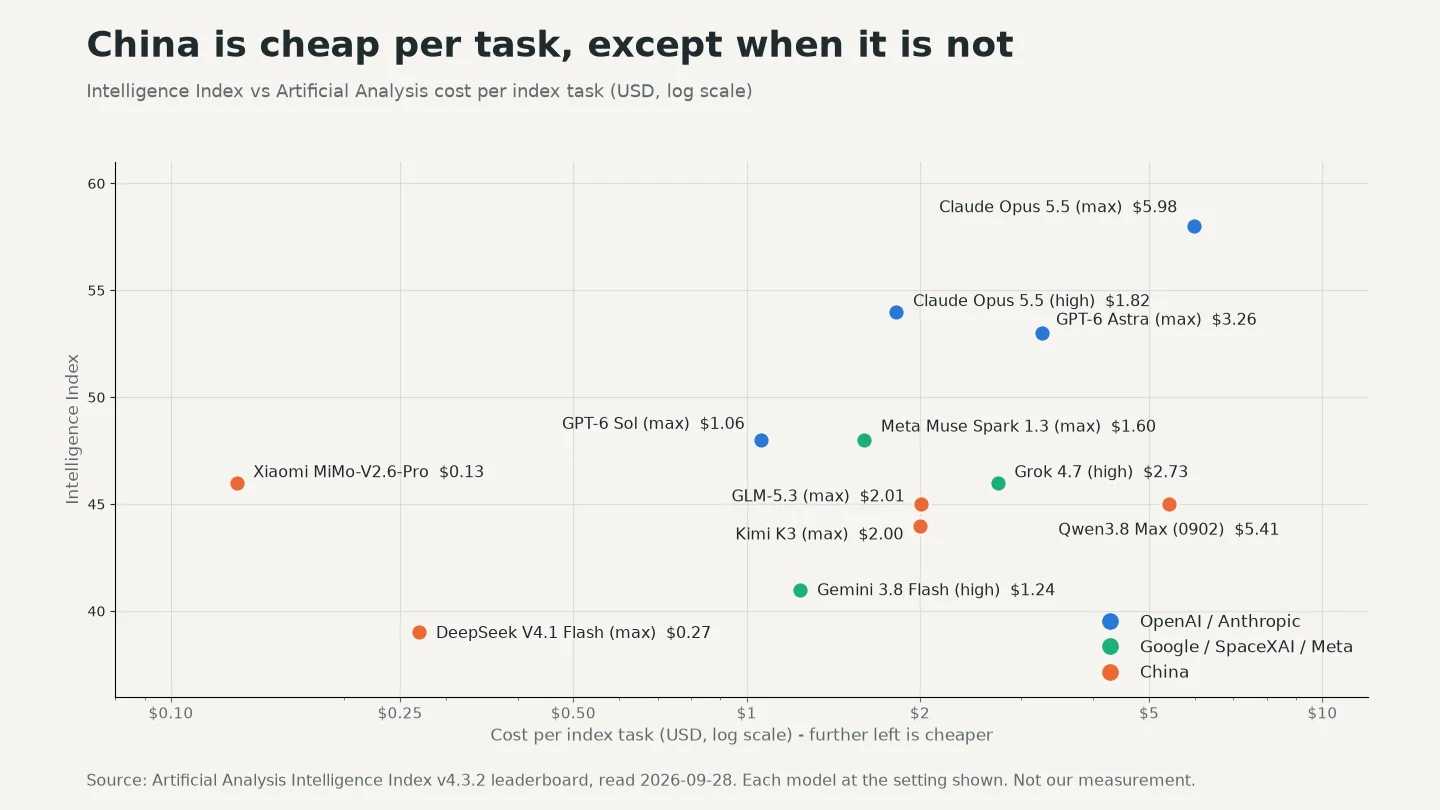
Source: Artificial Analysis — cost per Intelligence Index task at list prices, read September 28, 2026 — chart by HSL
- I had filed Chinese AI under "cheap", and that turns out to be half right
- Artificial Analysis also reports what one index task cost, including reasoning tokens and caching
- That is closer to a bill than a token rate, because a model that thinks longer pays for every extra token
- Xiaomi MiMo-V2.6-Pro scores 46 for $0.13 per task, about 1/14 of Opus 5.5 at high effort ($1.82 for 54)
- DeepSeek V4.1 Flash scores 39 for $0.27 and beats DeepSeek's own V4 Pro (36 for $0.67)
- DeepSeek says so too (SiliconANGLE), a rare case where the cheaper model is the better one
- Qwen3.8 Max costs $5.41 per task for 45, close to Opus 5.5 at max effort ($5.98 for 58)
- Its rate card is $2 / $6, the same as Grok 4.7, yet its task bill is twice Grok's, so the gap comes from token use
- GLM-5.3 ($2.01) and Kimi K3 ($2.00) also cost more per task than Opus 5.5 at high effort, while scoring 9 and 10 points lower
| Model | Maker | Input / output per 1M tokens | Open weights |
|---|---|---|---|
| Claude Opus 5.5 | Anthropic | $4 / $20 | No |
| GPT-6 Sol | OpenAI | $2 / $10 | No |
| Muse Spark 1.3 | Meta | $1.25 / $4.25 | No |
| Grok 4.7 | SpaceXAI | $2 / $6 (prompts under 200K) | No |
| Gemini 3.8 Flash | $0.75 / $3.75 until Dec 31, then $1.50 / $7.50 | No | |
| MiMo-V2.6-Pro | Xiaomi | $0.435 / $0.87 | Yes, MIT |
| Qwen3.8 Max | Alibaba | $2 / $6 (international) | No, only smaller Qwen3.8 models |
| GLM-5.3 | Z.ai | $1.40 / $4.40 | Yes, own license |
| Kimi K3 | Moonshot | $3 / $15 | Yes, own license |
| DeepSeek V4.1 Flash | DeepSeek | $0.15 / $0.60 off-peak, double at peak | Yes, MIT |
Sources: Anthropic, OpenAI, Meta, SpaceXAI, Google, Xiaomi via OpenRouter, Alibaba Cloud, Z.ai, Moonshot, DeepSeek and Hugging Face model pages, all checked September 28, 2026
- Kimi K3 lists at $3 / $15, more than GPT-6 Sol
- Open weights change that, and third-party hosts on OpenRouter sell K3 from $1 / $9 (OpenRouter)
- DeepSeek's peak hours are 01:00–04:00 and 06:00–10:00 UTC on weekdays, which is 10:00–13:00 and 15:00–19:00 in Seoul
- For a Korean office, the double rate lands right in working hours
Grok's rate card is half price; its task bill is not
- SpaceXAI, the name xAI took after merging into SpaceX, calls Grok 4.7 "half the price of comparable models" (SpaceXAI)
- Against Opus 5.5's $4 / $20, its $2 / $6 is half on input and 30% on output
- Per task, Grok 4.7 at high effort costs $2.73 for 46, while Opus 5.5 at high effort costs $1.82 for 54
- That makes Grok 1.5 times the bill for eight fewer points
- Meta's Muse Spark 1.3 is the better US deal here, at 48 for $1.60 per task
- Its Contributor tier cuts the price to $0.10 / $0.20, and Meta says that traffic is used to improve its products
- The 92% input discount is paid for with your prompts
- Meta keeps Muse Spark closed and has promised an open-weights release without a date (Meta)
- Its old open model, Llama 4 Maverick, scores 10 on the same index, and the top open-weights model is now Xiaomi's
Anthropic's report names every Chinese lab in this chart
- On September 10, Anthropic published a threat report accusing seven China-based labs of "illicit distillation", training their models on Claude's outputs without permission (Anthropic report, pp. 145–153)
- Alibaba, Moonshot, DeepSeek, Zhipu and Xiaomi are all on the list, along with SenseTime and MiniMax
| Lab | Model in this article | Exchanges Anthropic attributes |
|---|---|---|
| Alibaba | Qwen3.8 Max | Over 151 million, May–July 2026 |
| Moonshot | Kimi K3 | Over 23 million, May–July 2026 |
| DeepSeek | V4.1 Flash | Over 12.1 million in 14 days of July |
| Zhipu (Z.ai) | GLM-5.3 | Over 3.4 million in 17 days of June–July |
| Xiaomi | MiMo-V2.6-Pro | Over 400,000 in 20 days of March–April |
- Anthropic says Moonshot and DeepSeek relayed their own users' requests to Claude and showed the answers as their own, without telling those users
- It says DeepSeek, Xiaomi and Moonshot also fed conversations with their users into Claude, some with names, email addresses and company data
- These are Anthropic's findings, and I found no public response from the named labs
- China's internet regulator summoned all seven and is investigating DeepSeek and Moonshot over the user data, with no penalty decided, per The Information (The Next Web)
- Anthropic is also a competitor, and its CEO called for a crackdown on this kind of distillation in the same month (essay)
- If your prompts contain company code or customer data, the hosting question matters more than a few cents per task
- Open weights help here, because MiMo, DeepSeek, GLM and Kimi can run on your own servers or a host you trust
So who gets which job?
| My situation | What I would do |
|---|---|
| Bulk jobs where price decides | Test MiMo-V2.6-Pro or DeepSeek V4.1 Flash first, and schedule DeepSeek runs off-peak |
| Prompts include company code or personal data | Use open weights on my own servers or a trusted host rather than the maker's API |
| Want a US vendor below Opus prices | Try GPT-6 Sol ($1.06 per task for 48) or Muse Spark 1.3 on the standard tier |
| Tempted by Grok 4.7's $2 / $6 | Compare cost per finished task first; on this index it costs more than Opus 5.5 at high effort |
| Using Qwen3.8 Max, GLM-5.3 or Kimi K3 to save money | Check the actual bill, because per task they cost more than Opus 5.5 at high effort |
| Waiting for Google | Use Gemini 3.8 Flash for now; Gemini 4 has no date |
- My earlier same-prompt test of Astra and Opus 5.5 shows how to measure cost per finished task on your own work
Community Reactions
- An r/singularity user tried Muse Spark 1.3 through two providers and found it passable for Godot and documentation work but unreliable for math tutoring (Reddit)
- An r/LocalLLaMA developer said MiMo-V2.6-Pro missed several ways around git restrictions in one security-focused sandbox task (Reddit)
- Another r/LocalLLaMA user got a good MiMo-V2.6-Pro result on one task, but only after corrections and extra tokens (Reddit)
Q&A (Field Notes)
- Q. Who is actually third after OpenAI and Anthropic?
- On this index it is Meta at 48, but Grok 4.7 and MiMo-V2.6-Pro at 46 sit within the gap an effort setting can move
- Q. Which model here is cheapest per task?
- Xiaomi MiMo-V2.6-Pro at $0.13, and Qwen3.8 Max is the most expensive of the second tier at $5.41
- Q. Is it safe to send company code to a Chinese model's API?
- Anthropic alleges three of these labs relayed user conversations to Claude, so for sensitive code I would self-host the open weights instead
- Q. Why is Google in the second tier at all?
- Its best current model is a Flash model, it has no Pro newer than the 3.1 Pro preview, and Gemini 4 has no date
- Q. Does Meta's Contributor tier make Muse Spark the cheapest option?
- At $0.10 / $0.20 it is among the cheapest, but Meta uses that traffic to improve its products